Understand the chemistry
RDKit validates SMILES and computes eight interpretable features, including molecular weight, LogP, and polar surface area.
APPLIED MACHINE LEARNING · PORTFOLIO PROJECT
How well does a molecule dissolve in water? AquaScope connects chemical structure to predictive models—and makes the science visible.
Python / RDKit / scikit-learn / PyTorch / TensorFlow
1,059 unique benchmark molecules
3 machine-learning frameworks
212 held-out test molecules
01 / EXPLORE
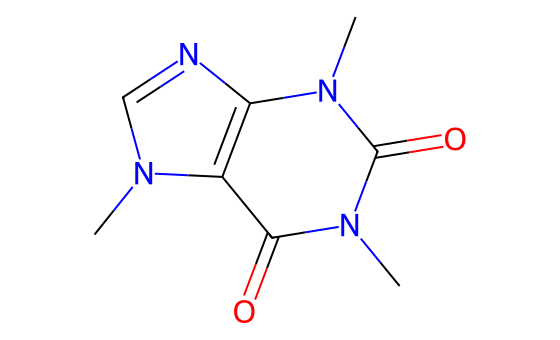
Choose a molecule to inspect a saved prediction from the project’s random forest. These are precomputed examples, not live inference.
RANDOM FOREST · SAVED OUTPUT
logS is log₁₀(solubility in mol/L). A one-unit increase means ten times the solubility. Estimates are educational, not laboratory measurements.
The full Python application accepts SMILES, renders structures, compares models, and exports predictions.
02 / EVIDENCE
One Delaney/ESOL benchmark. The same eight descriptors. A shared 60/20/20 train, validation, and test split, with seed 42.
| Model | MAE ↓ | RMSE ↓ | R² ↑ |
|---|---|---|---|
| Mean baseline | 1.788 | 2.212 | −0.034 |
| Random forest scikit-learn | 0.485 | 0.662 | 0.907 |
| Neural network PyTorch | 0.515 | 0.674 | 0.904 |
| Neural network TensorFlow | 0.524 | 0.691 | 0.899 |
MAE and RMSE are in logS units; lower is better. R² is unitless; higher is better. These are results from one random split, not a ranking of ML frameworks or proof of generalization to new chemical families.
Download recorded metrics ↗03 / ENGINEERING
RDKit validates SMILES and computes eight interpretable features, including molecular weight, LogP, and polar surface area.
scikit-learn supplies a baseline, random forest, splits, and scaling. PyTorch and TensorFlow implement independent neural networks.
Streamlit and Plotly turn the workflow into an interactive application with molecular drawings, test-set plots, and CSV exports.
Duplicate canonical structures are combined before splitting. Scaling uses training data only, and neural early stopping uses validation loss. Test molecules are reserved for reporting.
The model does not account for pH, temperature, crystal form, or measurement protocol. Related structures may appear in different partitions. Descriptor-range checks do not establish a validated applicability domain, and no calibrated confidence interval is claimed.
Data: Delaney (2004), ESOL, distributed by DeepChem. Benchmark data retains its own rights.